An 8 GB GPU can run useful local text models, but model file size is only part of the memory requirement. Start with a small quantized model. Keep room for context and the runtime. Measure memory use on your computer before you increase the context length.
Dataxad revised this guide on October 13, 2026. We removed speed claims that had no source and added file sizes from model publishers. We have not benchmarked these configurations for this guide. The June URL is the same.
Which local models are useful starting points for 8 GB VRAM?
The table lists text models with publisher-hosted GGUF files. GGUF is a model file format that runtimes, for example llama.cpp, can read. Q4_K_M is a quantization format that keeps much of the model at lower precision.
These are starting points to examine, not a ranking of all current models. File sizes use decimal GB and are rounded. They do not show peak VRAM or system RAM use.
| Model | Q4_K_M file | Evaluation starting point | Source |
|---|---|---|---|
| LFM2.5-1.2B-Instruct | 0.73 GB | Short extraction and classification tasks | Liquid AI files |
| Qwen3-4B | 2.50 GB | General text tasks with more free memory | Qwen files |
| Qwen3-8B | 5.03 GB | A larger candidate with less free memory | Qwen files |
The Liquid AI model card recommends its small model for extraction, tool use, and retrieval tasks. It does not recommend it for knowledge-intensive tasks or programming. Use that limit when you select your test prompts.
Qwen3-8B has thinking and non-thinking modes. Its native context is 32,768 tokens, with an extension method for longer context. Those limits do not mean that the full context fits on an 8 GB GPU. A short-context test must come first.
Why does a 5 GB model use more than 5 GB of VRAM?
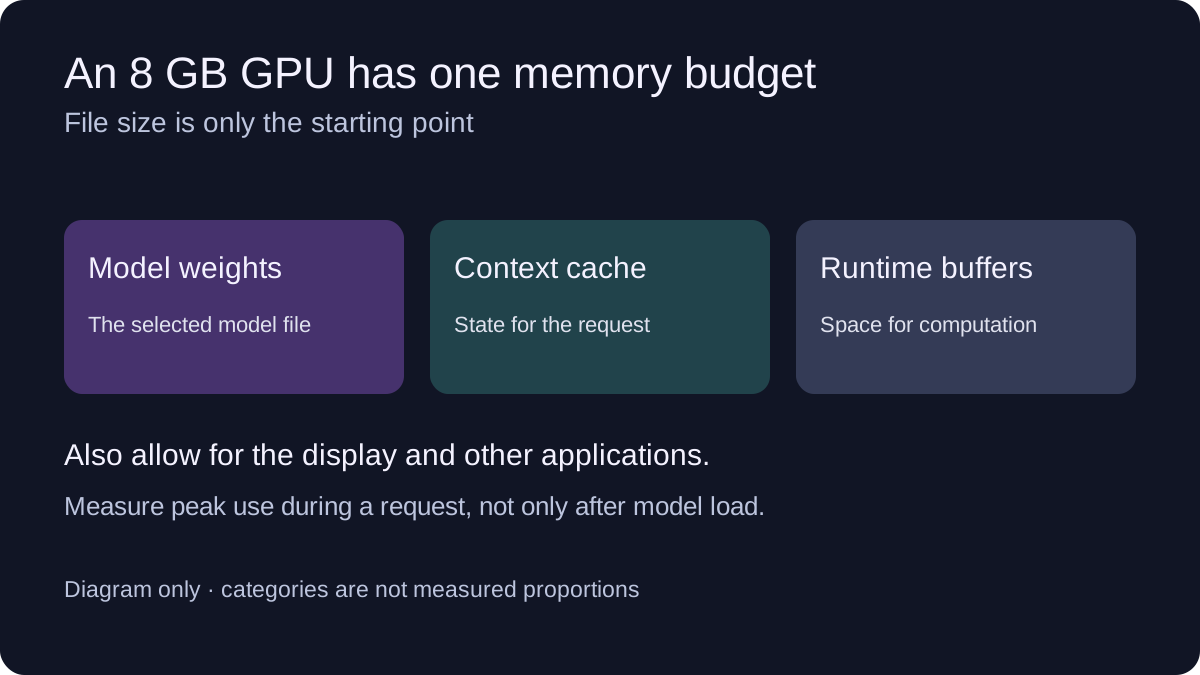
The model weights are only one allocation. The runtime also must have working buffers and memory for cached attention keys and values. This memory is the KV cache. Its size changes with the architecture, context length, data type, and number of concurrent requests.
A larger context can cause an allocation failure after the model starts correctly. A vision model can use more memory for image inputs. The text models in the table do not show a vision function.
No reliable rule says that all 8B models fit, or that all 4-bit files use the same memory. Start with the correct file and runtime. Measure peak memory during the full request, including when the model reads the prompt.
Is a 16 GB Mac equivalent to an 8 GB NVIDIA GPU?
No. An Apple Silicon Mac shares unified memory between the system, CPU, and GPU. A discrete NVIDIA GPU has its own VRAM, different from system RAM. macOS and other software use part of the Mac’s memory.
Apple’s MLX documentation gives its shared-memory architecture. MLX model files and GGUF files are different formats. Select a runtime and conversion that can run the model. Do not compare two file names as if they were measured runtime results.
A 16 GB Mac can be a good device to test small models. This guide does not promise that a model and context fit on each 16 GB configuration. Check memory pressure while the request runs.
How do I start with llama.cpp?
Use the llama.cpp installation instructions for your operating system and GPU backend. Its server can download models from Hugging Face and lets you set the context size.
This example uses the publisher’s Qwen3-4B Q4_K_M file and a 4,096-token context. The server documentation gives these flags.
llama-server -hf Qwen/Qwen3-4B-GGUF:Q4_K_M -c 4096 --host 127.0.0.1 --port 8080Open http://127.0.0.1:8080 after the server starts. Check the startup log for the backend and offloaded layers. A running server can use the CPU only. The command alone does not prove GPU acceleration.
This is a documented setup example, not a benchmark from this guide. Use the model card’s chat template and sampling guidance. Keep the server bound to the local computer unless you configure access controls for a network service.
What should I measure before choosing a model?
Use the same inputs for each candidate. Include short extraction, a document question, and a task from your usual work. Set an output limit. Record the correct and the incorrect results.
| Record | Why it matters |
|---|---|
| Model file and revision | Different conversions can produce different results |
| Runtime version and backend | A CPU run does not measure GPU performance |
| Context and output limits | Memory and speed depend on the request |
| Time to first token | Long prompt processing can delay the answer |
| Generation speed | Shows speed after the answer starts |
| Peak VRAM and system RAM | A successful load does not prove a full request fits |
| Correct results | Fast incorrect answers do not solve the task |
Check a short request first. Increase context in steps. Stop the increase if memory pressure increases or the runtime stops. Do the test again after you change quantization, runtime, or model revision.
Can Strata run a much larger model on a small GPU?
Strata uses a different method: GPU cache, CPU, system RAM, and an SSD lookup table. Its usual documented NVIDIA path uses 12 GB VRAM or more and substantial system RAM. The project also describes a slower 8 GB path. That does not replace the 8 GB starting points above.
Our Strata, REAP and oMLX guide gives those requirements. It also shows why offloading and pruning change different parts of the memory requirement. A smaller resident footprint does not prove faster responses or unchanged quality.
Does local inference keep all data on the computer?
A local inference runtime can read prompts on your computer. The software around it can also use web tools, telemetry, cloud providers, or remote storage. Check those connections before you use sensitive material.
Model files can also have different licenses. Read the correct model and conversion terms. Do not think that an open-source runtime gives the same rights for all models that it can run.
For a business deployment, specify the necessary outputs before you select hardware. Contact Dataxad to plan a small test with your documents, latency limits, and data requirements.